Sadhu — AI Q&A Service
A question-answering page where you asked a cartoon sadhu anything and a small language model running on the lab's own server answered.
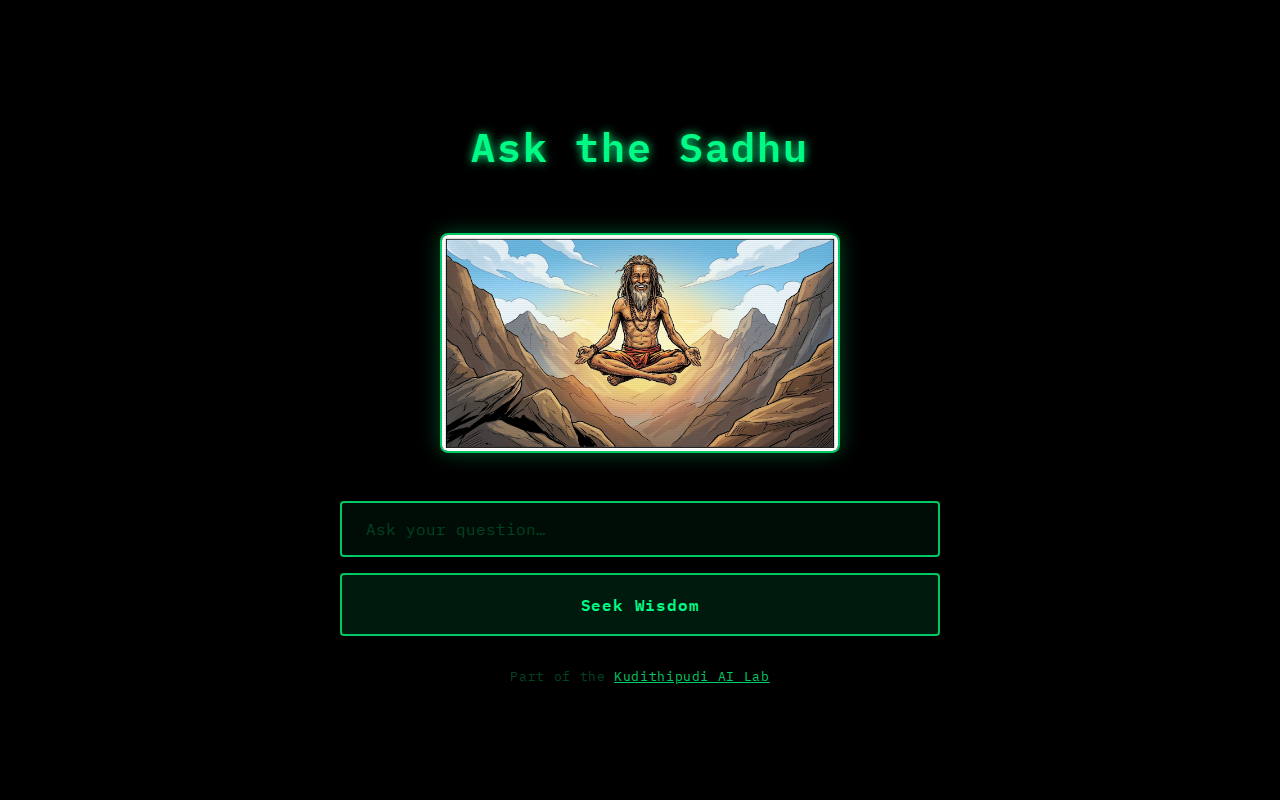
What it was
Sadhu was an experiment in running an LLM entirely locally: no API keys, no outside calls. A visitor typed a question, pressed Seek Wisdom, and got back a short answer in the sadhu's voice.
It ran HuggingFace's SmolLM2 with PyTorch on the server's CPU. The model was small enough to fit on a modest VPS but still needed around 3–4 GB of memory, more than any other lab app.
How it worked
- FastAPI app; the model loaded once at startup and inference ran in a worker thread so requests didn't block each other.
- Per-IP rate limiting on
/ask, backed by SQLite, kept one visitor from hogging the CPU. - Served by gunicorn + uvicorn on a unix socket behind nginx.
Built with
This project is retired and its server has been shut down. Its code and data are kept, so it can be brought back if needed. Browse the projects that are still running →